
 admin
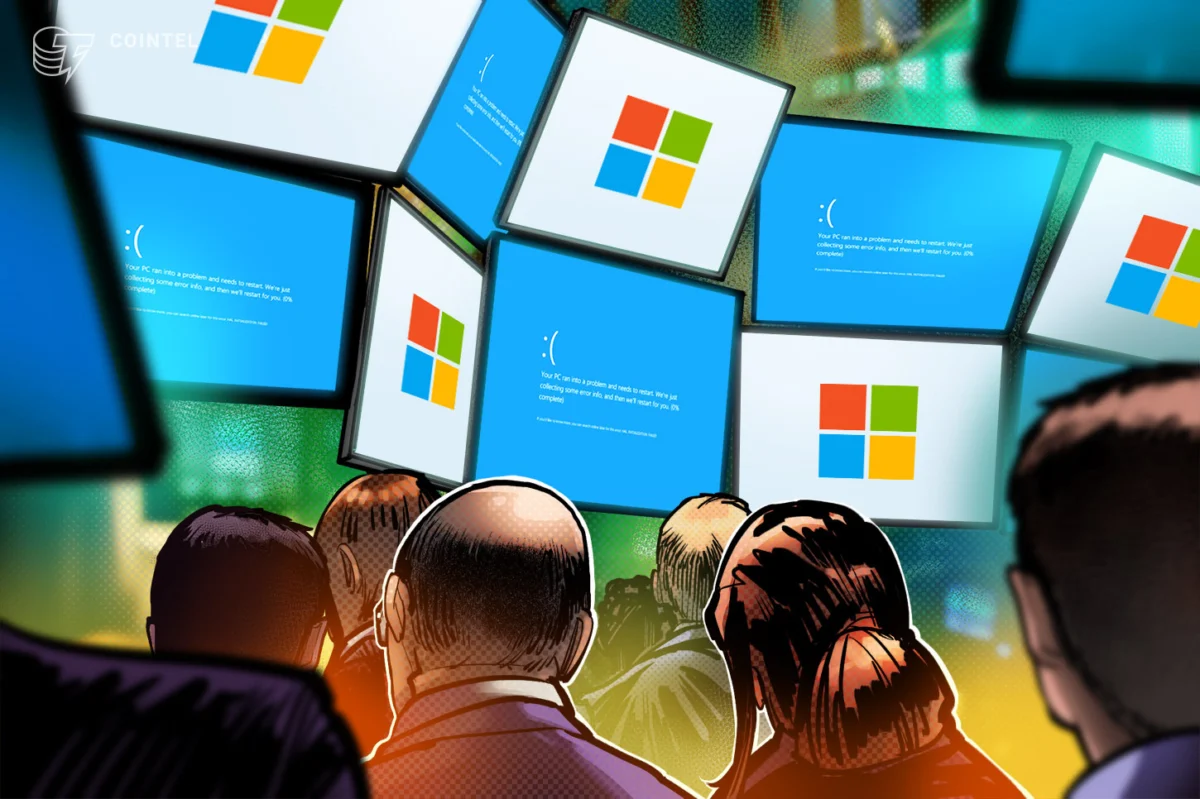
A widespread and severe global outage of Microsoft 365 services continued into Friday, November 13, 2026, causing significant disruption to essential government communications, enterprise productivity, and crucial integrations with leading artificial intelligence platforms like ChatGPT and Claude. The incident, which commenced on Thursday, left millions of users unable to access critical services such as Outlook email and various Microsoft Teams functionalities, underscoring the profound reliance of modern global infrastructure on cloud-based ecosystems. Microsoft initiated a broader patch rollout on Friday morning UTC, reporting improved stability on some affected servers, but a definitive timetable for full restoration remained elusive.
Chronology of a Cascading Disruption
The initial signs of trouble emerged in the early hours of Thursday, November 12, 2026, with reports of users in various Asia-Pacific regions experiencing difficulties accessing their Exchange Online mailboxes. As the day progressed, the outage rapidly expanded, affecting customers across Europe, the Middle East, and eventually North America. By late Thursday, the incident had escalated to a global scale, drawing widespread attention and concern from businesses, governmental bodies, and educational institutions alike.
Microsoft acknowledged the incident on its status pages, confirming that a specific process responsible for handling secure connections had become overloaded. This critical failure caused affected servers to cease processing requests, effectively locking users out of their mailboxes and other dependent services. Initial troubleshooting efforts by Microsoft included attempts to restore services by restarting core infrastructure components, redirecting network traffic to less congested pathways, and expanding server capacity. Despite these interventions, the outage persisted throughout Thursday, prompting Microsoft to issue a statement ruling out any indication of a security breach, a crucial detail to alleviate fears of cyberattacks amid the disruption.
As Friday, November 13, 2026, dawned, the outage continued unabated for many users. At 7:25 am UTC, Microsoft provided an update, republished by institutions such as the University of Pennsylvania, indicating that a patch had been developed and was being deployed. The company reported that this fix had begun to improve stability on some servers, signaling a potential turning point, but cautioned that a wider deployment was still underway. The absence of a clear timetable for complete service restoration, however, left many organizations grappling with ongoing operational paralysis.
Technical Roots and Microsoft’s Remediation Efforts
The root cause, as identified by Microsoft, was an overload within a process managing secure connections. In a complex cloud environment like Microsoft 365, secure connections are fundamental. They ensure that data transmitted between a user’s device and Microsoft’s servers is encrypted and authenticated, protecting sensitive information. An overload in this process can lead to a cascade of failures, where servers become unresponsive as they struggle to establish or maintain these secure links, effectively creating a bottleneck that chokes off service access. This type of failure, while not malicious, can be as disruptive as a targeted attack due to its systemic impact.
Microsoft’s response involved a multi-pronged technical approach. Restarting infrastructure components is a common first step to clear transient issues and restore service. Redirecting network traffic aims to route user requests away from congested or failing servers to healthier ones, a strategy often employed in large-scale distributed systems. Expanding server capacity involves provisioning additional resources to handle the load, which can be challenging during an active overload event if the core issue prevents new capacity from being properly integrated or utilized.
The deployment of a patch signifies a more targeted software-level fix designed to address the underlying vulnerability or inefficiency in the secure connection process. The incremental rollout of such patches is standard practice in hyperscale environments. A full, immediate global deployment carries risks of introducing new, unforeseen issues, so a phased approach allows Microsoft to monitor the patch’s effectiveness and stability on a subset of servers before wider application. This cautious methodology, while prolonging the restoration process for some, is crucial for ensuring the long-term integrity of the system.
Widespread Impact on Government, Enterprise, and Emerging AI
The far-reaching implications of the Microsoft 365 outage underscore the critical role these services play in global operations. With over 450 million paid commercial seats reported by Microsoft in an October filing, the suite serves as an indispensable digital backbone for businesses and government agencies worldwide.
Government Paralysis: Critical governmental functions were severely hampered. The US Court of Appeals for the Tenth Circuit reported that its clerk’s office was unable to send or receive email for a significant portion of Thursday, impacting legal filings, case communications, and administrative operations within the judiciary. Similarly, Japan’s Finance Ministry confirmed its inability to receive email on Friday, potentially disrupting vital economic communications, policy coordination, and international financial exchanges. In Singapore, the Government Technology Agency (GovTech) informed CNA that government email systems were among those affected, indicating potential disruptions to citizen services, inter-agency communications, and national security operations that rely on secure and timely digital correspondence. Such outages highlight the acute vulnerability of public sector bodies to cloud service disruptions, necessitating robust contingency planning.
Enterprise Productivity Downtime: Beyond government, countless businesses globally experienced significant operational paralysis. The inability to access Outlook email meant stalled internal and external communications, delayed project timelines, missed deadlines, and a substantial reduction in overall productivity. Specific functionalities within Microsoft Teams, such as scheduling meetings and sending invitations, were also affected, further hindering collaborative efforts. While most Teams calls and chats reportedly continued to function, the inability to organize new interactions or send critical follow-up invitations created a fragmented and inefficient work environment. For businesses, downtime translates directly into financial losses, reputational damage, and potential breaches of service-level agreements. Industry estimates often place the cost of IT downtime for large enterprises in the tens of thousands, if not hundreds of thousands, of dollars per hour, depending on the sector and criticality of affected systems.
Disruption to AI Integrations: A particularly noteworthy aspect of this outage was its impact on the burgeoning field of artificial intelligence. Both OpenAI’s ChatGPT and Anthropic’s Claude, leading generative AI platforms, reported errors in their respective Microsoft 365 connectors. These connectors are vital bridges that allow AI assistants to access and interact with a user’s enterprise data, such as emails, calendars, and documents, hosted within Microsoft 365. For instance, an AI assistant might use these connectors to summarize recent emails, schedule meetings based on calendar availability, or retrieve specific documents for information synthesis. The outage meant that most email, calendar, and search requests through Claude’s Microsoft 365 connector failed, and ChatGPT experienced similar errors. This disruption underscores the growing interdependence between foundational cloud services and advanced AI applications, revealing a new layer of systemic risk in the evolving digital ecosystem. As AI becomes more deeply integrated into daily workflows, the reliability of underlying cloud infrastructure becomes paramount for its effective and uninterrupted operation.
Broader Context: Cloud Reliance and Systemic Vulnerability
This global Microsoft 365 outage serves as a stark reminder of the world’s increasing reliance on a handful of hyperscale cloud providers. Microsoft’s commanding presence in the enterprise software market means that a disruption to its services has a ripple effect across vast swathes of the global economy and public sector. The benefits of cloud computing – scalability, cost-efficiency, global accessibility – are undeniable, but they come with the inherent risk of centralized points of failure. When a single provider experiences an issue, the consequences can be catastrophic for millions of users simultaneously.
Historically, cloud outages, while relatively infrequent given the scale of operations, are not unprecedented. Major incidents affecting AWS, Google Cloud, and even previous Microsoft services have periodically highlighted the fragility of these interconnected digital infrastructures. These events often prompt organizations to review their business continuity plans, consider multi-cloud strategies, or invest in hybrid solutions that combine on-premise and cloud resources to mitigate risk. However, for many, especially smaller enterprises and government agencies with limited IT budgets, diversifying critical services across multiple vendors remains a significant challenge.
The incident also raises questions about the transparency and communication protocols during such widespread outages. While Microsoft consistently updated its status pages, the absence of an immediate estimated time of restoration can be particularly frustrating for organizations trying to manage the fallout and inform their stakeholders. Clear and consistent communication is paramount in maintaining trust during crises of this magnitude.
Implications and Future Outlook
The Microsoft 365 outage carries several significant implications for the future of cloud computing, enterprise operations, and AI integration:
- Reinforced Need for Resilience: Organizations will undoubtedly re-evaluate their disaster recovery and business continuity plans. This might include exploring offline capabilities for critical data, implementing redundant communication channels, or accelerating moves towards multi-cloud or hybrid IT architectures for truly mission-critical functions.
- Scrutiny on Cloud Provider Reliability: While Microsoft maintains high reliability standards, such a widespread and prolonged outage will inevitably lead to increased scrutiny from customers, industry analysts, and potentially regulators. The emphasis will be on root cause analysis, preventative measures, and improved incident response protocols.
- Interdependence of Digital Ecosystems: The impact on AI connectors highlights the intricate web of dependencies in the modern digital landscape. As AI tools become more integrated with enterprise data, the stability of foundational cloud services becomes a prerequisite for the effective functioning of advanced AI applications. This incident underscores the need for robust APIs and fallback mechanisms for AI services that rely on external data sources.
- Economic Cost of Downtime: The cumulative economic impact of this outage, while difficult to quantify immediately, will be substantial. Lost productivity, delayed transactions, and the diversion of IT resources to crisis management all contribute to significant financial burdens for affected entities.
- Governmental Digital Sovereignty: For government agencies, the outage might reignite discussions around digital sovereignty and the extent to which critical public services should rely on commercial cloud providers, particularly foreign ones. This could lead to increased investment in national cloud infrastructures or more stringent contractual requirements for cloud service level agreements.
As Friday progresses, the world watches for further updates from Microsoft regarding the full restoration of its services. This incident serves as a potent reminder of the fragility of our increasingly digital world and the paramount importance of robust, resilient, and transparent cloud infrastructure. The long-term lessons learned from this widespread disruption will undoubtedly shape future strategies for both cloud providers and their vast global customer base.